OpenAI and Microsoft Advance AI Governance and Evaluation Frameworks
OpenAI publishes updated model values for AI alignment, while Microsoft deploys synthetic enterprise data to evaluate Copilot without compromising privacy.
Published
October 31, 2026
Reading time
4 minutes
Perspective
Research
Topics
AI governance · synthetic data · speech recognition
On October 29, 2026, OpenAI released an updated Model Spec defining five core values to direct advanced AI toward sound judgment, human agency, and fidelity to human intent. Simultaneously, Microsoft Research disclosed its Industry Evaluation Data Generation Platform, a synthetic environment system that replicates enterprise workflows using public data sources like O*NET, job postings, and SEC filings—enabling rigorous Copilot evaluation without accessing sensitive customer data. Both initiatives address critical challenges in AI deployment: alignment with human values and scalable, privacy-preserving testing.
OpenAI formalizes AI alignment values
OpenAI’s updated Model Spec explicitly outlines five core values intended to guide the development of more capable AI systems toward sound judgment, human agency, and faithfulness to human intent. This is a direct, official announcement from OpenAI’s channel, confirming a structured framework for ethical alignment. The document does not specify the five values, nor does it detail implementation mechanisms or enforcement protocols. It serves as a declarative policy statement rather than a technical specification.
Source: An updated Model Spec for more capable and beneficial AI · OpenAI News
Microsoft uses synthetic enterprise tenants for Copilot evaluation

Microsoft built full-scale synthetic enterprise environments, termed 'tenants,' to evaluate Copilot without using real customer data. These tenants simulate organizational structures, communication patterns, and time-evolving workflows using grounded public data from O*NET, job postings, and SEC filings. Each environment includes realistic users, meetings, emails, and documents. Automated safety checks ensure no personally identifiable or harmful content is generated. The platform enables testing of time-aware queries like 'What did the team decide last Thursday?'—a capability absent in generic benchmarks.
Source: From synthetic enterprise data evaluations to real Microsoft Copilot AI confidence · Microsoft Research
MIT-affiliated leaders publish AI insights anthology
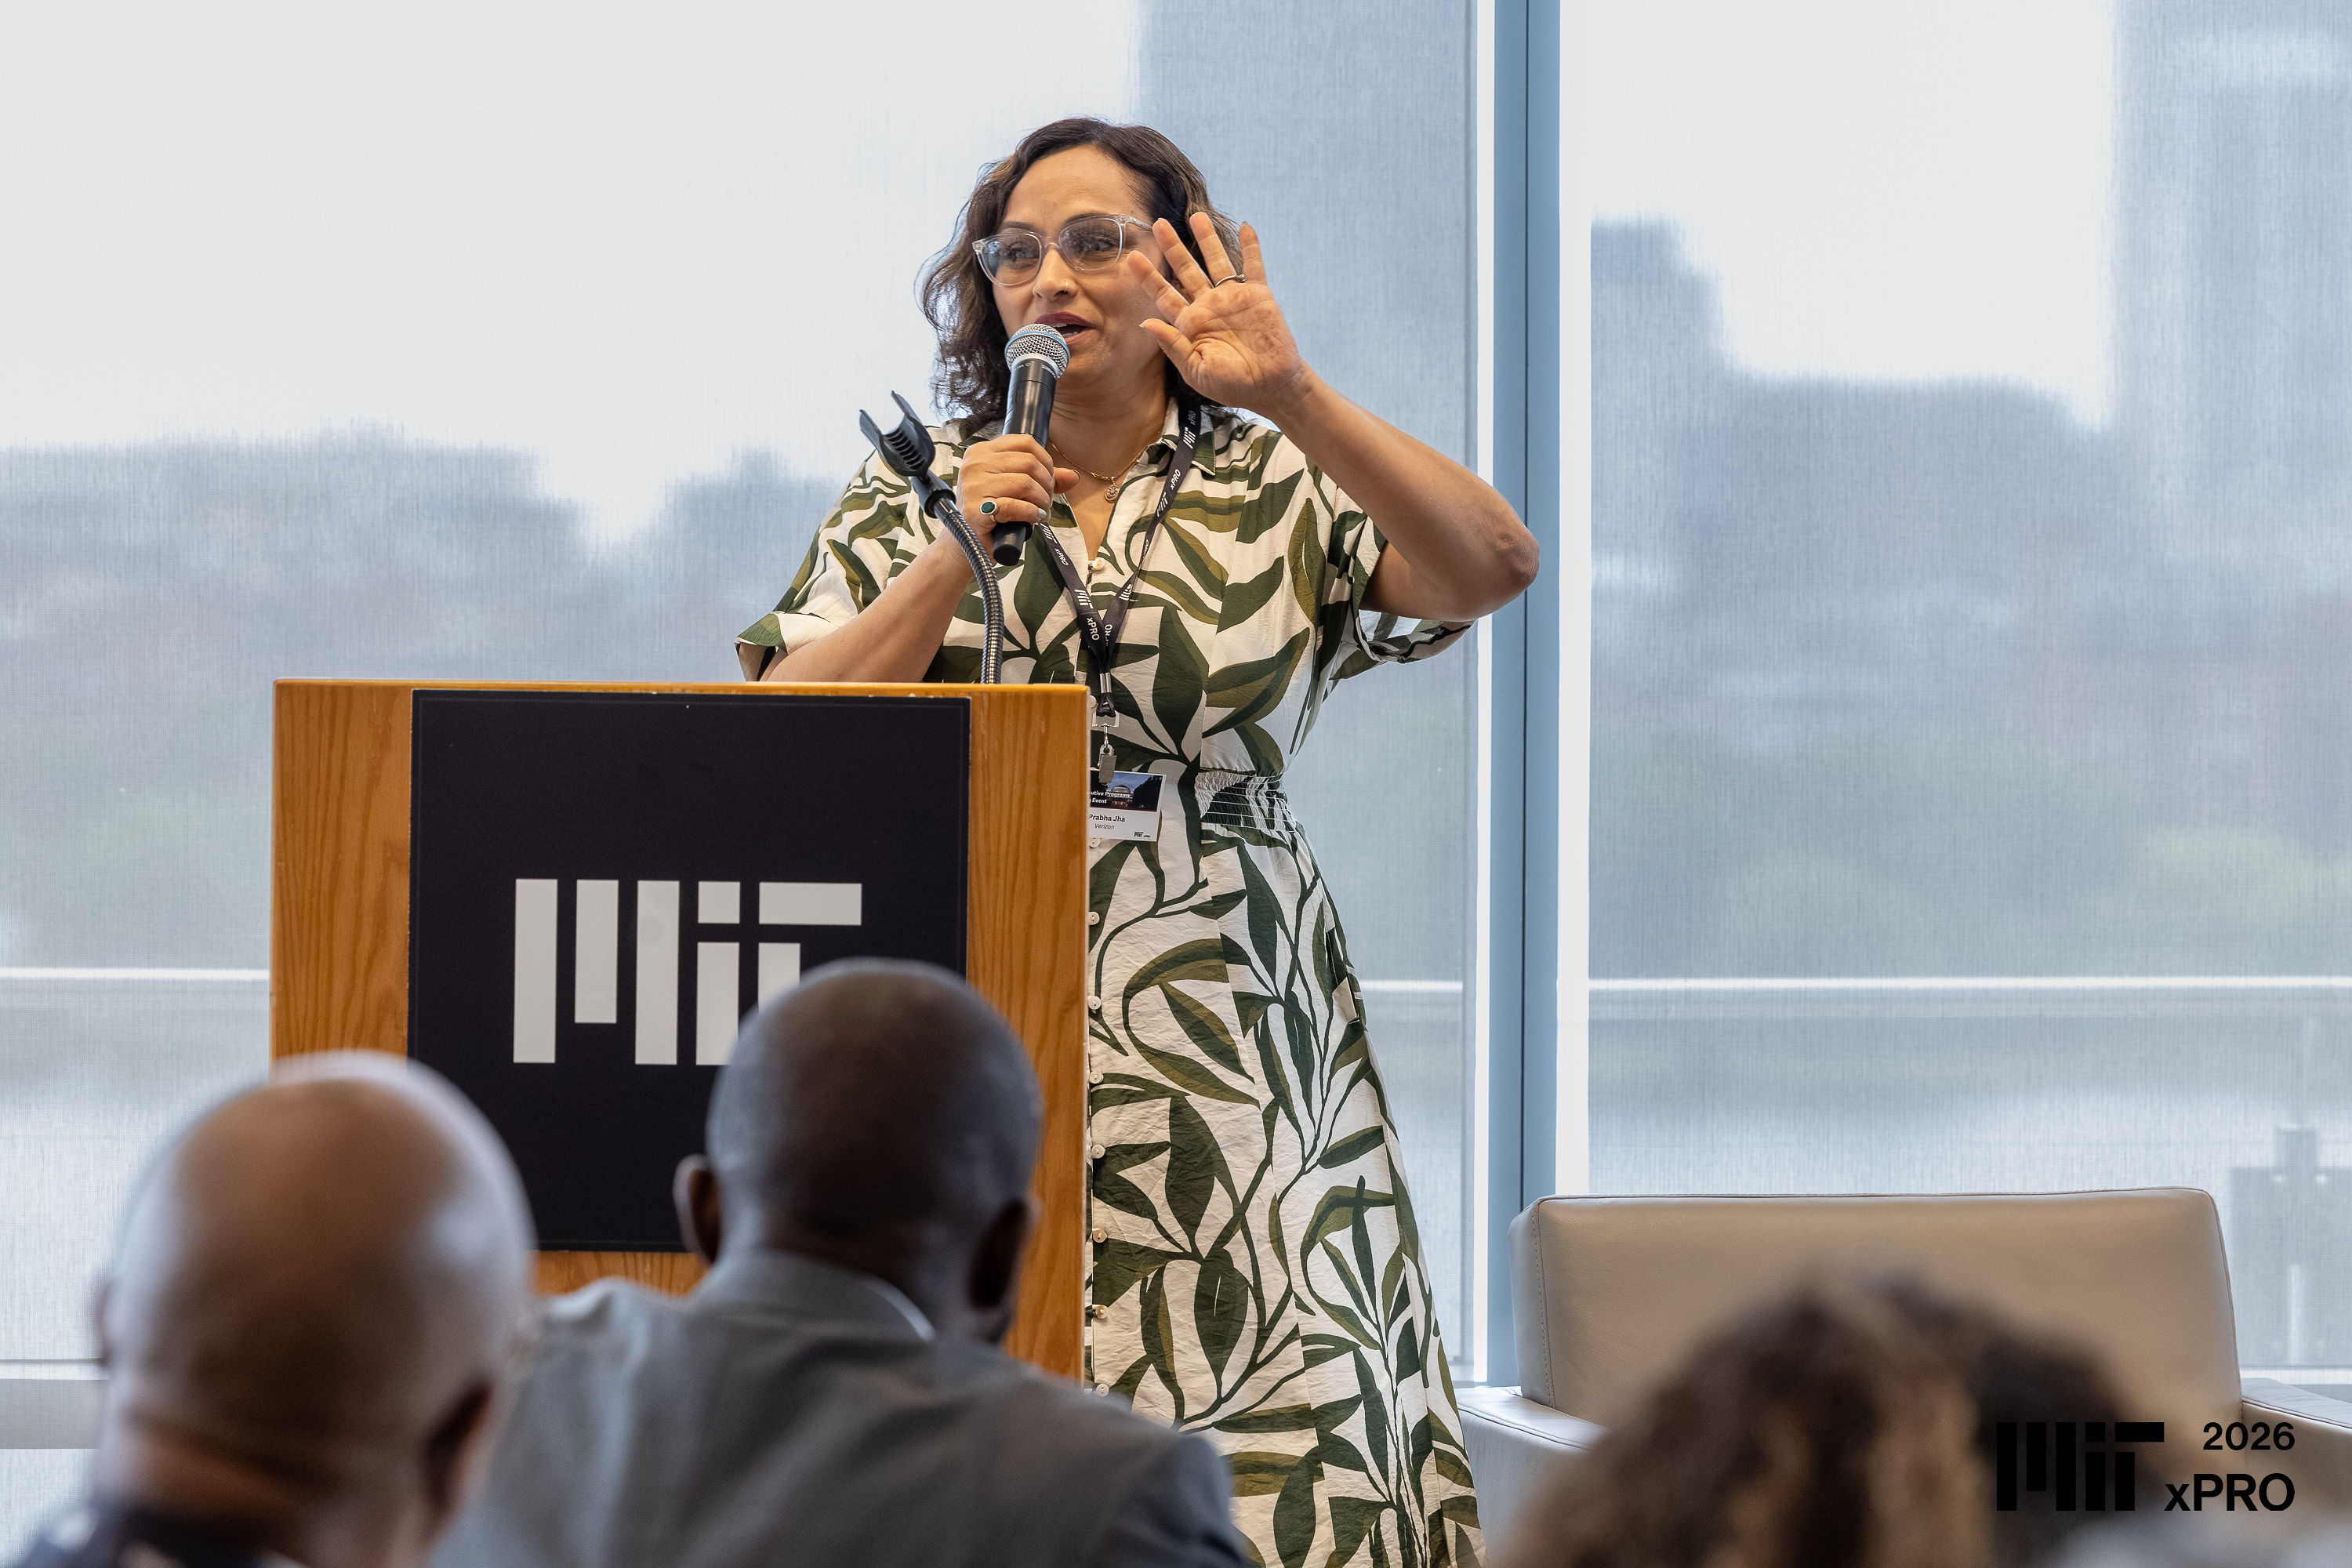
Prabha Jha, alongside 20 peers from MIT Open Learning’s AI for Senior Executives program, co-authored 'The AI Anthology,' a collection of essays on AI’s societal and industry-wide impacts. The book emerged from peer discussions during an in-person program, with one participant’s story about using AI to combat Alzheimer’s inspiring the project. The anthology emphasizes human-centered perspectives beyond cost-cutting and efficiency, urging leaders to consider quality of life and fulfillment. No specific essays or contributors beyond Jha are named in the excerpt.
Source: Learner collaborates with MIT peers to develop book of AI insights · MIT News · AI
OpenAI matches Anthropic’s API credit offering for premium subscribers
OpenAI has introduced API credits for subscribers on $100, $200, and $500 monthly ChatGPT plans, matching Anthropic’s recently announced benefit. Subscribers receive credits equivalent to their plan’s monthly cost, usable within one API organization. The benefit is explicitly tied to existing subscription tiers and does not extend to free or lower-tier users. Simon Willison confirms this is a direct parallel to Anthropic’s policy, with no mention of credit expiration terms or usage restrictions beyond the implied time-limited nature of 'expiring credits.'
Source: API credits benefit for eligible ChatGPT subscriptions · Simon Willison
NVIDIA releases offline speech model with one-H100 deployment requirement

NVIDIA launched Nemotron 3.5 Transcribe, a 30B-parameter offline speech model supporting transcription, translation, and audio question answering across 40 languages. The model accepts audio up to one hour and outputs speaker-attributed transcripts with optional timestamps. The official README specifies one H100 80 GB GPU as the deployment configuration for the BF16 checkpoint. The model does not support real-time streaming, and performance benchmarks are limited to selected datasets. FP8 and NVFP4 variants exist but are not part of the open-source release.
Source: NVIDIA Nemotron 3.5 Transcribe: A Complete Guide to the Speech AI Model · HackerNoon · AI
Frontier model selection hinges on cost, consistency, and task fit

A HackerNoon analysis notes that eight frontier models score within six points on the Artificial Analysis Intelligence Index, yet their cost-per-task varies by up to 11x—e.g., GPT-6.1 Sol at $0.72 vs. Claude Fable 5.1 at $7.63. Accuracy and consistency differ significantly: Gemini 4 Argon and GPT-6 Astra both score 53, but hallucination rates are 15% vs. 51%. The analysis stresses that benchmark scores alone are insufficient; product teams must measure task completion rate, error impact, and migration cost. Switching models requires manual testing, not automatic updates.
Source: How to Choose the Right Frontier AI Model for Your Product · HackerNoon · AI
What to watch next
These developments reflect a maturing AI ecosystem where governance, evaluation, and deployment are increasingly decoupled from proprietary data and constrained by hardware and cost realities. OpenAI and Microsoft prioritize alignment and privacy-preserving testing, while NVIDIA and Anthropic/ OpenAI focus on accessible but resource-intensive tools. Meanwhile, real-world adoption is shaped by practical trade-offs between performance, cost, and reliability—not just model rankings.
Continue reading