LLM Integration Simplifies Datasette-Agent Setup
datasette-llm 0.1a9 removes the need to manually configure a default LLM model for Datasette Agent, streamlining deployment.
Published
November 1, 2026
Reading time
4 minutes
Perspective
Research
Topics
LLM integration · software trust erosion · malware targeting
Simon Willison released datasette-llm 0.1a9, a plugin update that enables Datasette Agent to automatically inherit the default LLM model configured in its parent environment. Previously, users had to explicitly set the model via command-line flags such as -s plugins.datasette-agent.default_model gpt-6-astra. The new version eliminates this step by detecting the default model from the LLM environment, reducing configuration friction for developers deploying the tool. This change is purely operational, affecting only the initialization workflow without altering functionality or model capabilities.
Automatic model detection in datasette-llm
The datasette-llm 0.1a9 update allows the plugin to detect and use the default LLM model already set in the environment, removing the requirement to manually specify it via -s plugins.datasette-agent.default_model. This change reduces user configuration burden but does not introduce new model options, alter inference behavior, or expand supported models. The update is backward compatible and only affects the initial setup phase. No performance metrics or usage statistics are provided to measure adoption or impact.
Source: datasette-llm 0.1a9 · Simon Willison
LLMs erode trust in software documentation
Kyle Kingsbury observes that LLM-generated content undermines traditional signals of software maturity, such as accurate documentation and reliable maintenance practices. Engineers may now treat new projects with suspicion, as previously trusted indicators—like well-documented APIs or stable release cycles—can be artificially generated. This shift does not describe a technical vulnerability but a cultural erosion of trust signals. No specific incidents or data are cited to quantify the scale of this effect.
Source: Quoting Kyle Kingsbury · Simon Willison
Malware uses LLMs to prioritize high-value victims
A malware variant has been observed using LLMs to rank potential victims based on estimated financial worth, enabling targeted exploitation. This represents a shift from broad, indiscriminate attacks to selective, economically motivated targeting. The malware likely analyzes system metadata, user behavior patterns, or network context to assign value scores. No technical details about the model architecture, training data, or deployment method are disclosed. The threat is operational, not theoretical, and exploits existing supply chain vulnerabilities.
Source: Malware uses LLMs to rank victims by how much they're worth · Hacker News
France’s Albert API remains in development for sensitive workloads

France’s Albert API, a shared gateway to generative models for public sector use, is still finalizing its approved version for internal state data. While the platform supports open-weight and proprietary models and offers functions like OCR and document classification, its readiness for sensitive workloads is not yet confirmed. DINUM’s documentation explicitly states that authorization for handling classified or personal public data is pending. No deployment logs, audit trails, or performance benchmarks are available to verify operational readiness.
Source: France’s AI Strategy: Turning Models, Compute, and Public Investment Into National Capability · HackerNoon · AI
MIT fellows focus on AI2050’s core challenges
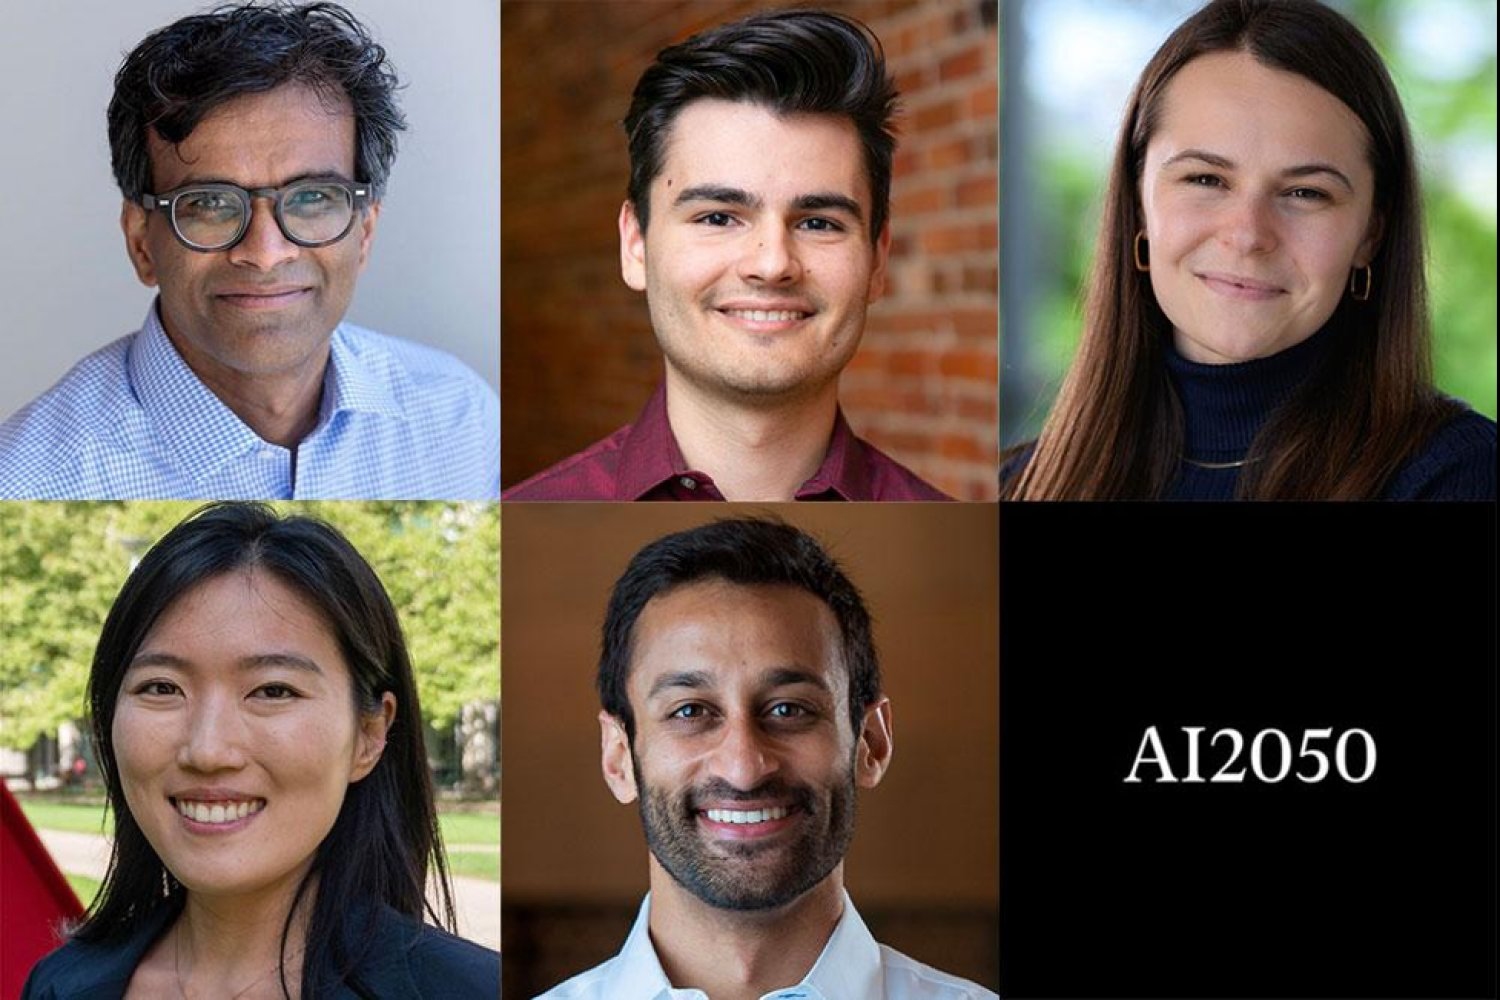
Seven MIT-affiliated researchers were named AI2050 Fellows to address foundational questions about beneficial AI by 2050. Their projects include translating AI-detectable patterns into testable theories, improving model training efficiency, designing democratic participation tools, determining enzyme functions via AI, and mitigating harms in algorithmic hiring. Each project is explicitly framed around long-term societal outcomes, not technical benchmarks. No funding amounts, timelines, or success metrics are disclosed beyond the fellowship designation.
Source: MIT affiliates named 2026 Schmidt Sciences AI2050 Fellows · MIT News · AI
Microduck’s voice identity is derived from processor serial numbers

Each Microduck robot produces a unique sonic identity generated from its processor’s serial number, ensuring no two units emit identical sounds. This feature is designed to simulate individuality and foster emotional attachment, but the robot does not experience emotion. The software is open source and supports sim-to-real transfer via cloud-based reinforcement learning. The robot’s 15-motor system runs on a compact battery with limited autonomy, and its behavioral training occurs in virtual environments before deployment. No data on user attachment metrics or long-term interaction studies are provided.
Source: Microduck, the Robot Pet That Imitates Life: Can We Really Grow Attached to a Machine? · HackerNoon · AI
What to watch next
The convergence of simplified tooling, adversarial LLM use, institutional AI deployment, and robotic embodiment reveals a fragmented landscape where operational convenience, security risk, and societal impact evolve independently. Each development operates within its own boundary: one improves developer workflow, another exploits supply chains, a third navigates bureaucratic procurement, and a fourth simulates companionship—all without systemic coordination.
Continue reading