Agent Lightning Enables Real-World Harness Training Without Reimplementation
Microsoft Research introduces Agent Lightning v1.

Published
October 7, 2026
Reading time
4 minutes
Perspective
Research
Topics
reinforcement learning · on-device AI · baseline modeling
Microsoft Research Asia has released Agent Lightning v1.0, a 3,500-line framework that implements Harnessed Agentic RL—a paradigm where the same agent harness used in production directly participates in training. This approach removes the need to reimplement agent logic inside RL frameworks, which previously caused discrepancies between trained and deployed agents. The system uses an LLM proxy to intercept model calls from the agent harness, recording prompts, responses, and log probabilities without altering existing code. It supports native Kubernetes job execution on self-managed or cloud infrastructure, with no reliance on commercial sandbox services.
Harnessed Agentic RL eliminates deployment-training mismatch
Agent Lightning v1.0 introduces Harnessed Agentic RL, where the agent harness—responsible for context management, tool invocation, and execution logic in deployment—is reused during training. This contrasts with traditional RL systems that require rebuilding the agent loop within the training framework, often altering behavior. By placing an LLM proxy between the agent and model, Agent Lightning observes and records interactions without modifying the harness, ensuring the trained agent mirrors the deployed one. This directly addresses the risk of performance degradation due to implementation drift between training and production environments.
Source: Agent Lightning v1.0: A 3,500-Line Lightweight Agentic RL Framework for Training Agents with Real Harnesses · Microsoft Research
EmbeddingGemma 2 enables on-device multimodal embeddings

Google DeepMind released EmbeddingGemma 2, a 740M-parameter multimodal embedding model that unifies text, code, images, audio, and video into a single embedding space. Built on Gemma 4, it supports dynamic vector truncation via Matryoshka Representation Learning, reducing storage by up to 6x. The model runs on consumer hardware like the Google Pixel 11 Pro with as little as 191MB RAM for text-only use and 567MB for full multimodal inference. It achieves state-of-the-art performance among sub-1B models on MTEB Code and MAEB benchmarks, enabling offline semantic search and retrieval without cloud dependency.
Source: EmbeddingGemma 2: an open, lightweight multimodal embedding model · DeepMind Blog
Majority-class baselines reveal true model value in classification tasks
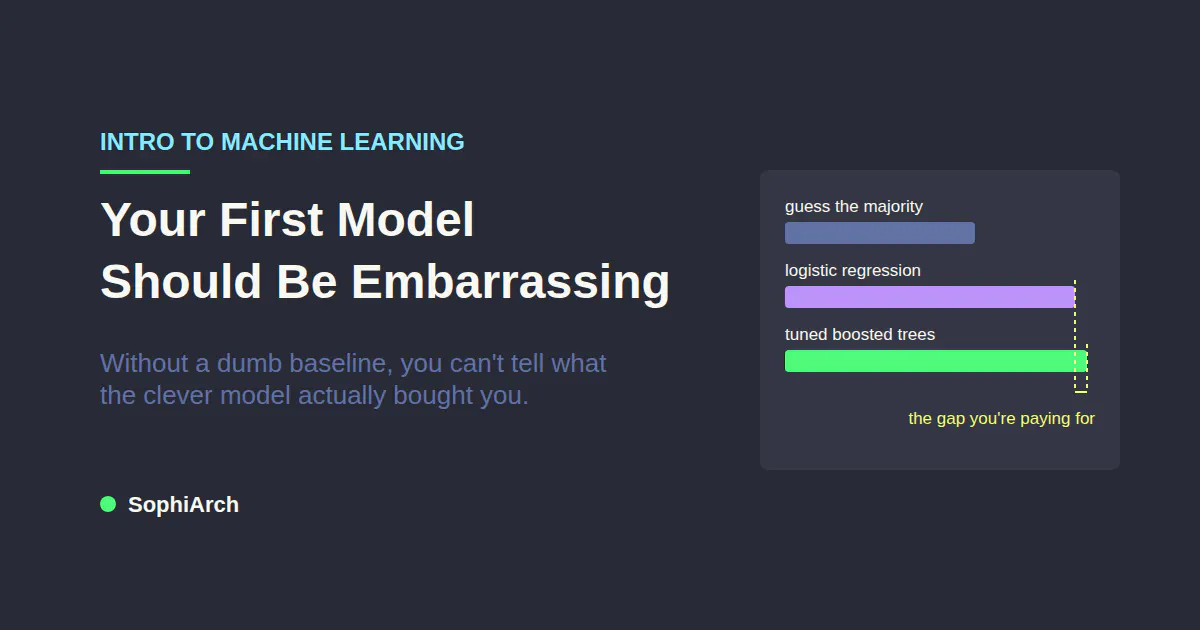
Analysis of six public binary classification datasets shows that a majority-class guess model often achieves accuracy levels exceeding 85%, such as 95.3% on the hypothyroid dataset. Logistic regression, even without tuning, frequently improves performance by less than 1 percentage point over this baseline. Default gradient-boosted trees outperform logistic regression by 2–15 AUC points, but hyperparameter tuning adds less than 0.5 AUC gain on five of six datasets. Without comparing against these simple baselines, improvements from complex models may be misattributed or overstated, especially in imbalanced datasets where accuracy is misleading.
Source: Your First Model Is Going to Be Embarrassing - And That's Okay · HackerNoon · ML
Persistent AI agents blur player and coach roles in gaming
Emerging platforms like SIMA and Voyager demonstrate agents that retain skills across multiple virtual environments, moving beyond single-game optimization. These agents accumulate experience, store reusable behaviors, and operate via screen input and action output, mimicking human interaction. The shift suggests a future where players own and evolve persistent agents across games, transforming gaming from controlling a character to coaching an intelligent entity. This redefines player identity: the human becomes the curator of an agent’s memory, strategy, and adaptation, not the direct actor.
Source: Your Next Main Isn't Human · HackerNoon · AI
Enterprise AI requires governance over capability
Swapneswar Sundar Ray of US Bank emphasizes that enterprise AI systems must prioritize security, observability, audit trails, and human oversight over raw performance. He notes that while agentic AI can reason and invoke APIs, its deployment in regulated environments demands runtime guardrails, authorization controls, and accountability mechanisms. The focus shifts from making models more capable to ensuring they remain aligned with organizational policies, comply with regulations, and allow for human intervention—especially in high-stakes domains like finance.
Source: An Interview with Swapneswar Sundar Ray, Assistant Vice President & Principal ML Engineer at US Bank · HackerNoon · AI
LLM adaptation requires choosing between fine-tuning and RAG
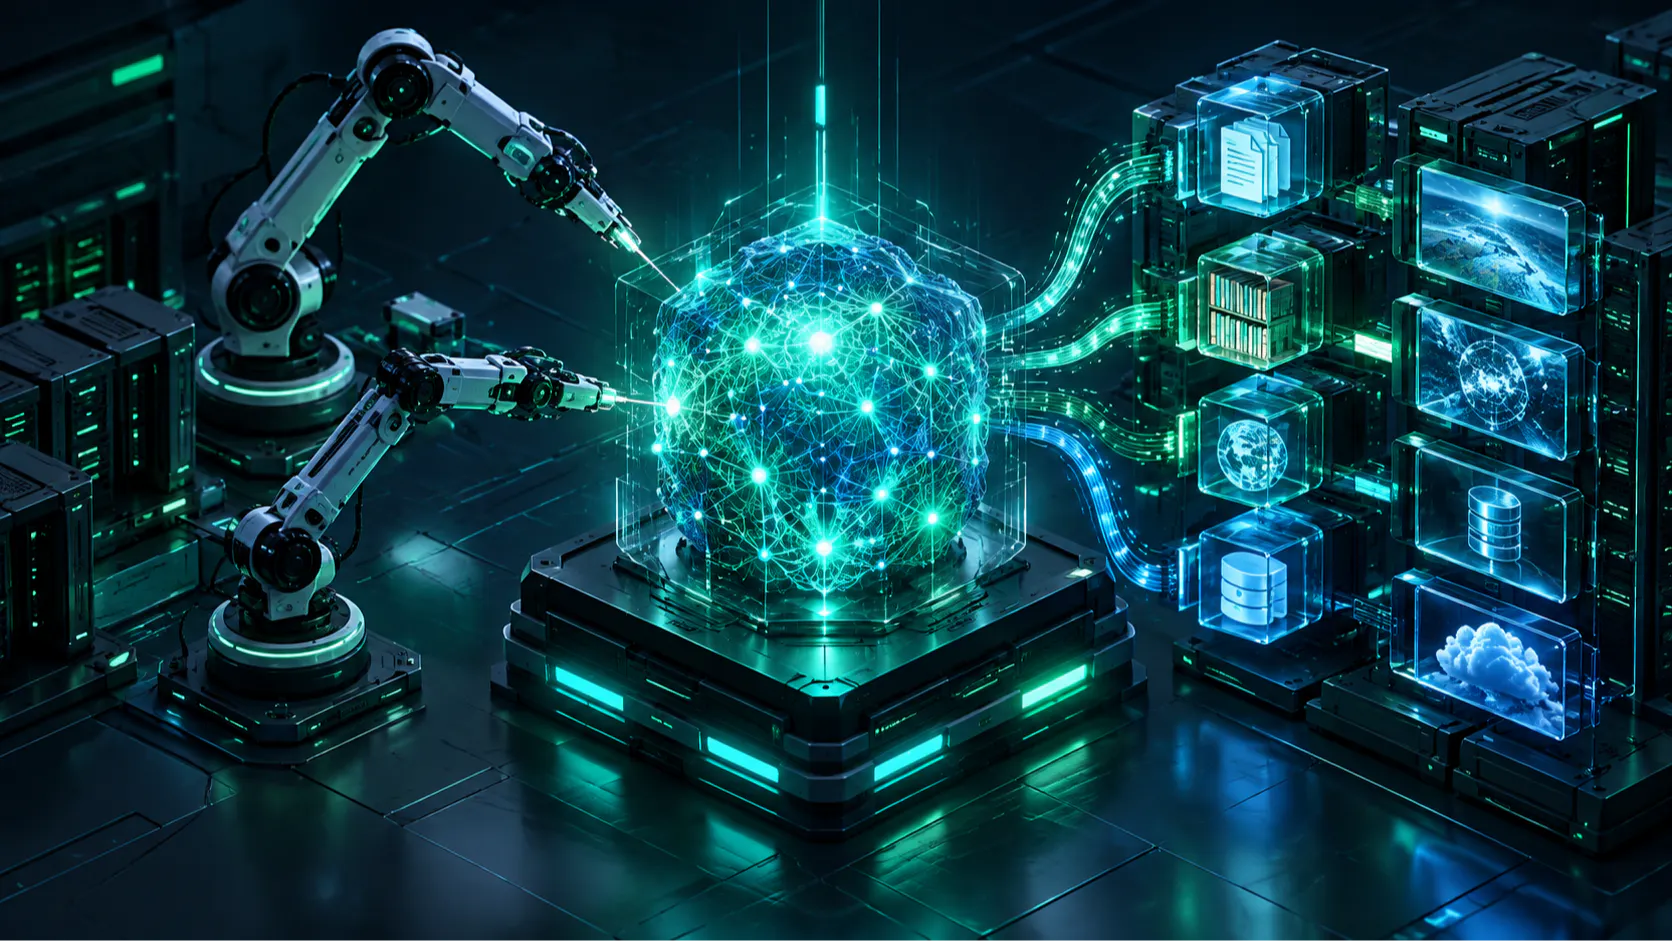
The article distinguishes fine-tuning—modifying internal model weights—as suitable for domain-specific knowledge, while RAG (Retrieval-Augmented Generation) dynamically retrieves external data for context. It notes that while LLMs excel at general reasoning, their performance in specialized domains often depends on this architectural choice. The decision is not merely technical but operational: fine-tuning requires retraining and versioning, while RAG demands robust retrieval systems and data freshness. Neither is universally superior; the choice depends on data volatility, update frequency, and compute constraints.
Source: The LLM Operating System: Transformers, Limitations, and the Need for Adaptation · HackerNoon · ML
What to watch next
These developments collectively reflect a maturation in AI engineering: frameworks now prioritize fidelity to real-world deployment (Agent Lightning), on-device efficiency (EmbeddingGemma 2), empirical rigor in evaluation (baseline models), persistent agent identity (gaming), governance in enterprise use, and deliberate architectural trade-offs in LLM adaptation. Each signal underscores a move away from abstract model performance toward system-level reliability, accountability, and practical deployment constraints.
Continue reading