StudentSim Simulates Learner Responses to Improve AI Tutor Research
Microsoft Research introduced StudentSim, which uses de-identified learner records to evaluate AI tutoring systems before human studies.

Published
October 12, 2026
Reading time
4 minutes
Perspective
Research
Topics
AI tutoring · student simulation · agent memory
Microsoft Research developed StudentSim as a research tool to evaluate AI tutoring systems using personalized simulators trained on publicly available, de-identified learner records. The system does not replace human testing or classroom instruction. It trains each simulator in two stages: first learning common patterns across pooled domain data, then adapting to individual student records. This approach addresses the slow pace and high cost of human studies by providing feedback on whether a tutor’s guidance alters a student’s behavior, measured through behavioral fidelity and guidance responsiveness.
StudentSim evaluates tutors using two education-grounded metrics
StudentSim measures tutor effectiveness through behavioral fidelity—whether the simulator matches a student’s past responses—and guidance responsiveness—whether the simulator changes its behavior after receiving tutor input. These metrics are grounded in Vygotsky’s zone of proximal development. The system was evaluated across chess, second-language English writing, and mathematics, and outperformed leading baselines in providing feedback signals for tutor training. It is not designed to predict learning outcomes but to simulate how a specific student might respond to guidance.
Source: Simulating student learning for better AI tutoring · Microsoft Research
AI agent memory requires validity tracking beyond semantic retrieval
HackerNoon argues that AI agents can make incorrect decisions when retrieving memories that were once true but are no longer valid. The issue is not retrieval failure but the absence of lifecycle metadata such as valid_from, valid_until, or status fields like SUPERSEDED. Semantic similarity alone cannot distinguish between historical truth and operational truth, leading agents to act on outdated information even when the memory is accurately retrieved and grammatically correct.
Source: The Most Dangerous Memory in an AI Agent Is the One That Used to Be True. · HackerNoon · AI
Online surveillance policies target compliant users, not cybercriminals
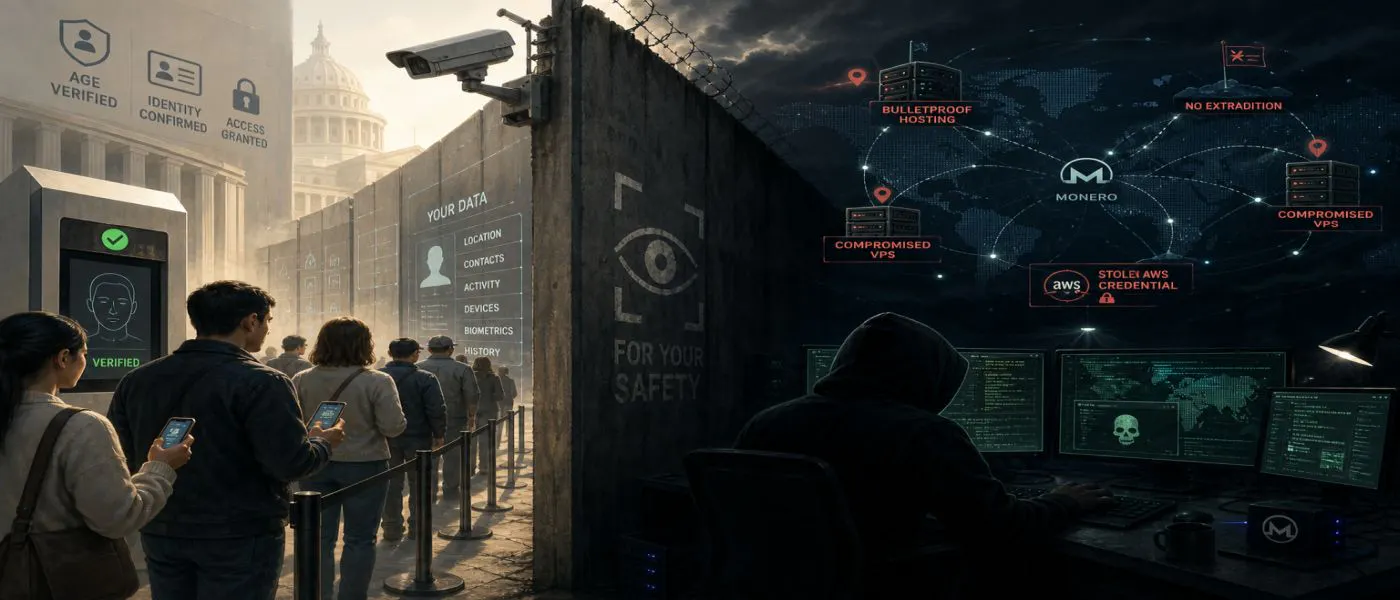
Governments expanding digital ID, age verification, and metadata retention claim these measures improve safety, but HackerNoon observes they primarily affect law-abiding users. Cybercriminals bypass such systems using stolen identities, offshore infrastructure, or encrypted channels. The EU’s invalidated Data Retention Directive exemplifies how broad surveillance creates permanent centralized capabilities that extend beyond their original purpose, with no measurable impact on the actual threat actors.
Source: The Safer Internet Lie: Why More Surveillance Isn't Making Anyone Safer · HackerNoon · AI
Humanity’s Sixth Sense benchmark reveals AI’s visual reasoning gaps
The Humanity’s Sixth Sense benchmark tests AI models on 522 questions requiring intuitive reasoning about visual scenes, such as spatial fit or causal dynamics. Human performance averages 93.1% pass@1. The best AI model, GPT-6 Astra, scores 53.6% pass@1. Common failures include missing critical details (21% of errors) and misidentifying objects (20%). The benchmark does not compare models by region or claim open-weight models lack emergent understanding.
Source: Import AI 476: Creativity and RSI; worse-than-China open weight models; AI goes to space · Import AI
Brazil bans prediction markets over manipulation and regulatory gaps
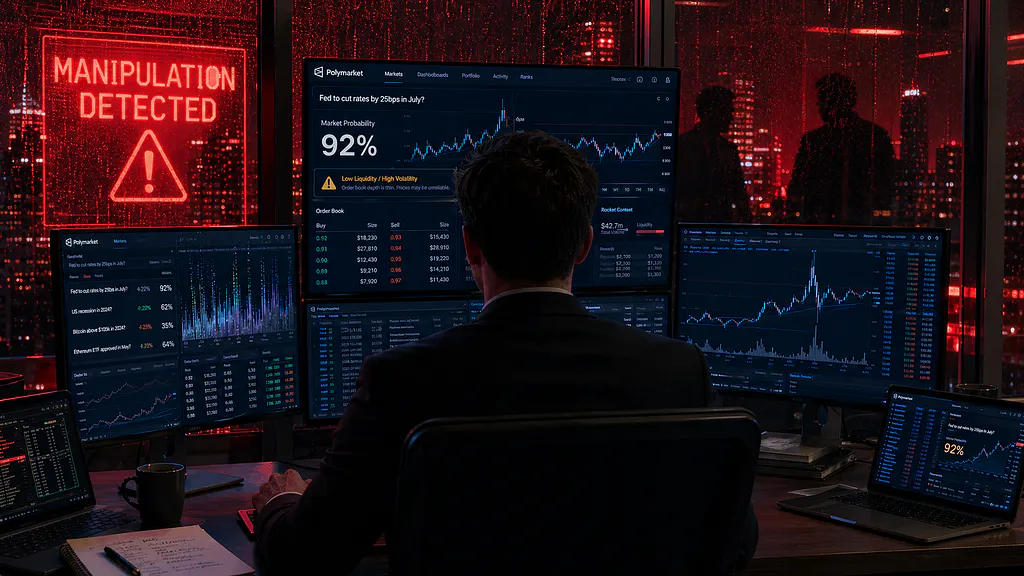
Brazil’s central bank prohibited prediction markets like Polymarket and Kalshi, citing investor protection and market integrity. The ban follows documented cases of manipulation, including artificially altering sensor readings to influence weather bets and insiders using classified military information to profit. Regulators classified these platforms as illegal gambling due to the absence of real-time surveillance, position disclosure, or consistent resolution protocols for manipulated outcomes.
Source: Why Countries Are Cracking Down on Polymarket and Kalshi · HackerNoon · ML
datasette-ports 0.4 adds PID display for local instance profiling
Simon Willison released datasette-ports 0.4, which detects all running Datasette instances on a machine and lists their ports alongside process IDs (PIDs). This enables users to attach Python 3.15’s profiler directly to specific instances for performance analysis. The update supports the latest Datasette versions and provides practical utility for developers managing multiple local data services without requiring external monitoring tools.
Source: datasette-ports 0.4 · Simon Willison
What to watch next
These developments reflect distinct technical challenges in AI systems: simulating human behavior for research, managing temporal validity in memory, addressing surveillance asymmetry, recognizing limitations in visual reasoning, regulating manipulable markets, and improving developer tooling. Each operates within defined boundaries and does not imply broader systemic shifts.
Continue reading